QIIP (QUADS Idle Inference Proxy) is a QUADS-native inference proxy and tractor beam for idle GPU hardware: it pulls free NVIDIA GPU equipped bare-metal systems with no current active QUADS schedules (non-QUADS systems can be manually added via the interface), then serves them through one OpenAI-compatible endpoint.
What It Does
- One gateway, one API: a single unified inference endpoint backed by many GPU nodes
- User access control: Google OAuth (SSO), admin roles, and per-user scoped tokens
- Token tracker: every request tracked per token and per model
- Bring your own inference: tenants attach and dedicate their own hardware to their team
- Automatic plumbing: engine install, drivers and CUDA, NFS, firewall, monitoring, teardown
- Ultra Efficiency: only free, unscheduled systems join the pool, and they cycle back out on any new schedule
Features
| Feature | Why it matters |
|---|---|
| OpenAI-compatible gateway | One endpoint for all inference: /v1/chat/completions, /v1/completions, /v1/models, streaming |
| Only free, unscheduled systems | Pulls in completely free NVIDIA hosts with no QUADS schedule; they stay free to QUADS and can be self-scheduled |
| Ultra Efficiency | Cycles spare capacity in and out, expanding and shrinking the inference pool as systems free up or get rescheduled, even for self-scheduled workloads |
| Routing that self-heals | Least-connections load balancing, failover, circuit breakers, continuous health checks |
| Engine setup by GPU layout | Reads the node’s GPU model/VRAM/count, then builds and configures vLLM or llama.cpp (SHA-256 verified) |
| No model guesswork | llmfit + HuggingFace give hardware-aware model picks and ranked recommendations |
| Bare-metal provisioning | BMC power, NVIDIA driver, CUDA, NFS, firewall, health poll, registration, all automated |
| User access control | Google OAuth SSO, local admin, admin roles, endpoint-scoped qiip_ tokens (SHA-256, revocable) |
| Token tracker | Per-token and per-model usage reporting on your profile |
| Bring your own inference | Tenants dedicate their own GPU hardware to their team, with private endpoints |
| QUADS-native | Polls QUADS inventory, unified node view, auto-teardown on scheduling conflicts |
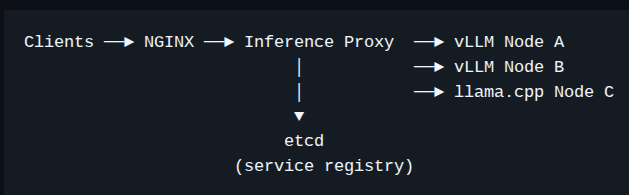
Architecture
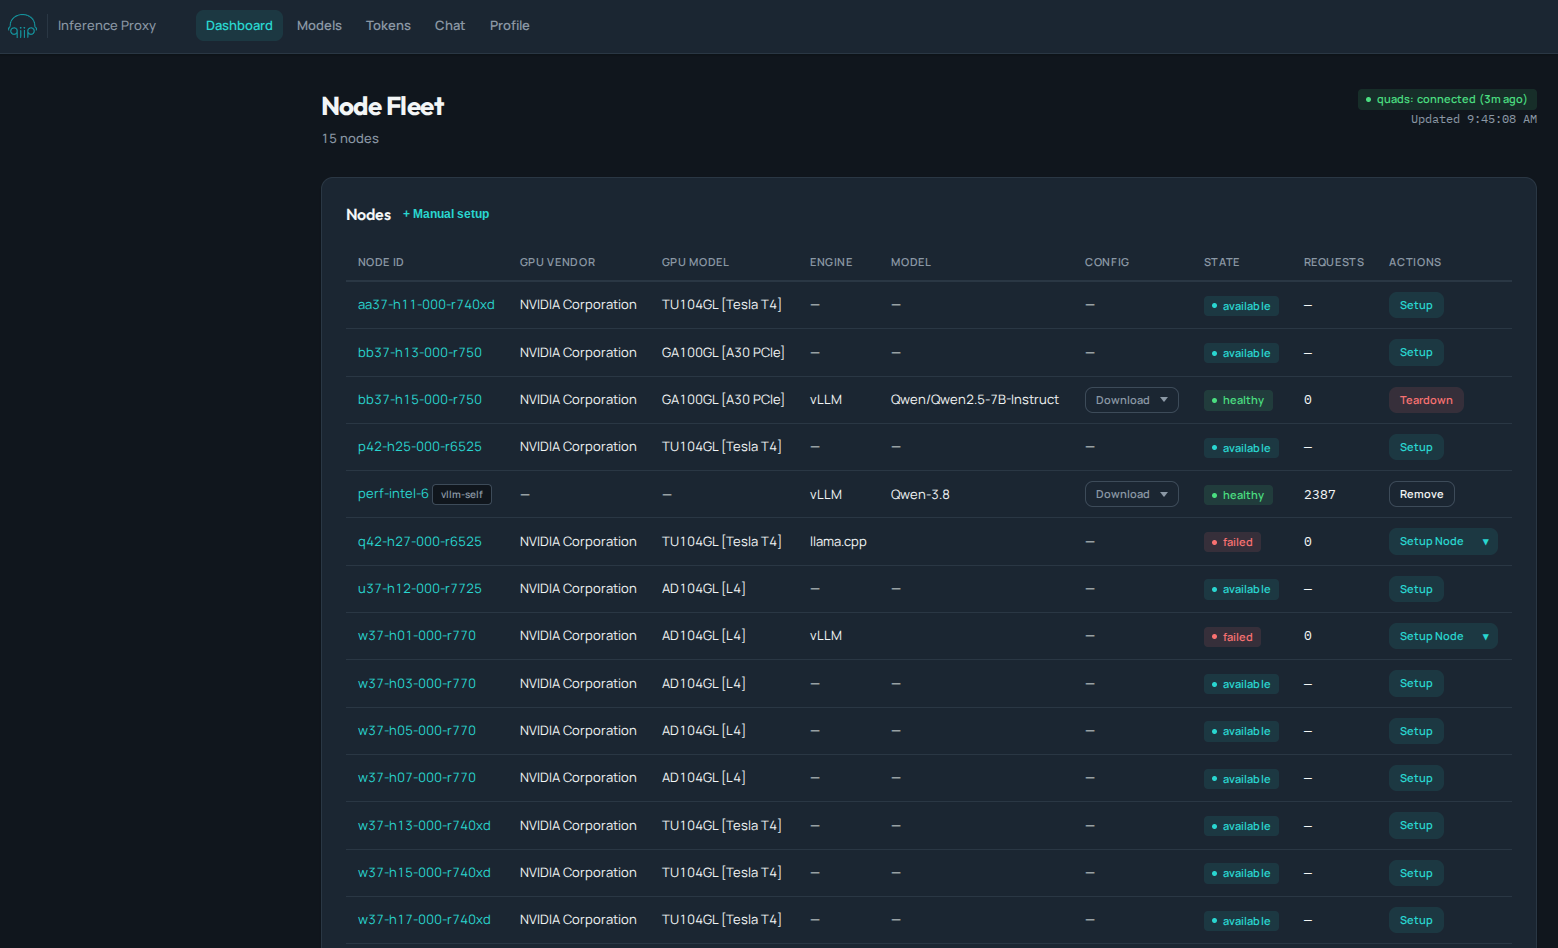
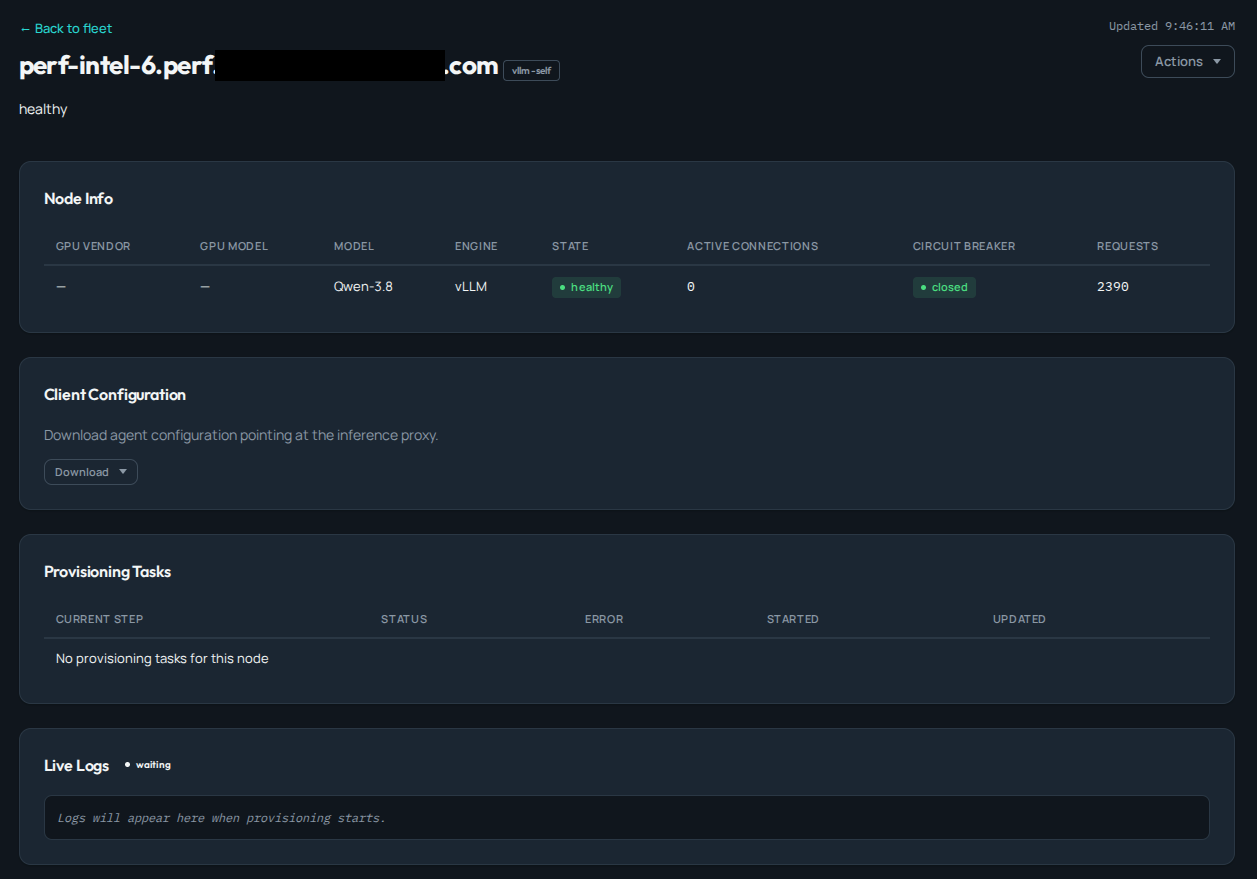
Dashboards
Project Details
| Language | Python 3.12/3.13 | License | GPLv3 |
| Engines | vLLM, llama.cpp | Model fitting | llmfit + HuggingFace |
| Discovery | etcd | Runtime | FastAPI, Uvicorn, Pydantic v2 |
| Auth | Google OAuth, local admin, API tokens | Automation | asyncssh, Redfish BMC |
| Docs / CI | Github, Actions | Contact | Github, #quads |
Core Development Team
- Gonza Rafuls (project lead) – @grafuls
- Will Foster – @sadsfae
- Sebastian Jug – @sjug
- Kambiz Aghaiepoour – @kambiz-aghaiepour
 QUADS Project
